Psst. Want me to read this one to you?
Tap me or the button.
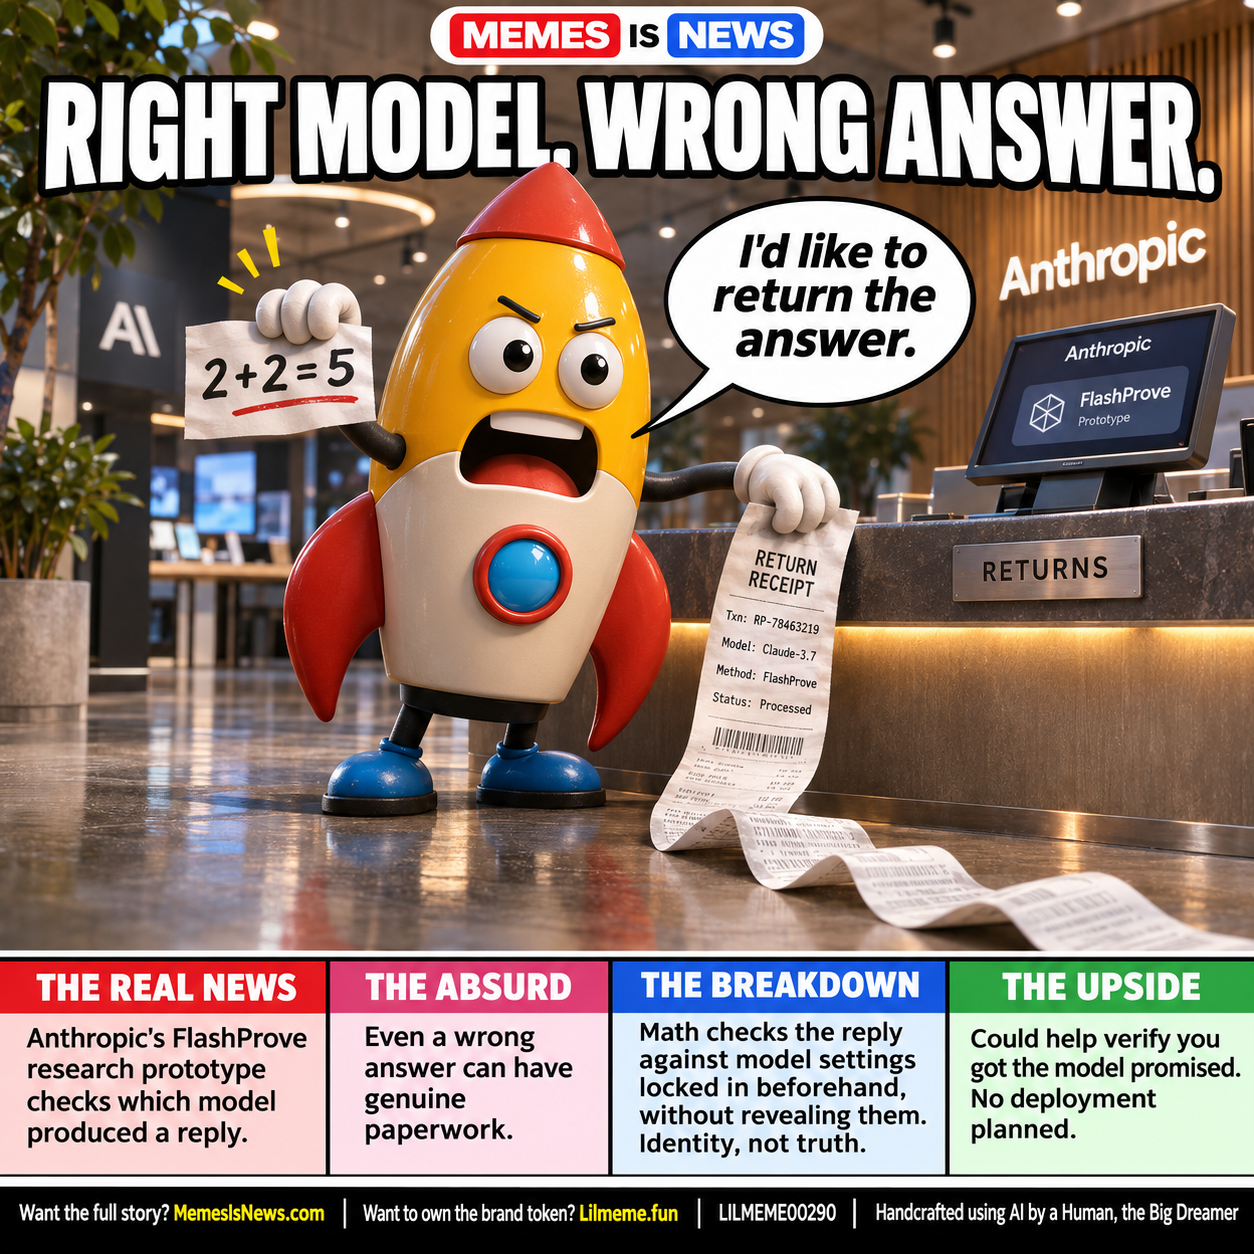
RIGHT MODEL. WRONG ANSWER.
A receipt proves where you bought something. It doesn't prove your purchase was sensible. Anthropic is researching a similar distinction for AI answers. An AI model uses internal ...
The real news
The story, straight
A receipt proves where you bought something. It doesn't prove your purchase was sensible.
Anthropic is researching a similar distinction for AI answers.
An AI model uses internal numbers, called weights, to turn your question into a reply. Different weights mean a different model.
A name above a chat box isn't mathematical evidence of which model answered.
FlashProve, Anthropic's open-source research prototype, lets a provider lock in an exact set of weights beforehand through a mathematical fingerprint. A proof can then show that those weights produce the reply, without revealing the weights themselves.
Think of it as checking the kitchen that made your meal, not whether dinner tastes good.
That distinction is the joke: a confidently wrong answer could pass the identity check. The proof doesn't establish truth, usefulness or safety.
In our imaginary returns department, Lil'meme has brought back an incorrect answer with immaculate paperwork. Unfortunately, customer service can authenticate his disappointment.
This isn't a feature arriving in your Claude chat. Research is ongoing, and there are no plans to deploy FlashProve at Anthropic or any other lab.
The published demonstration used Meta's Llama 4 Maverick, not Claude. It also checks a specific integer-based calculation method, not every way a chatbot can generate text.
The useful possibility: users could check whether a reply matches the model promised, without receiving its private weights. That's accountability for the machinery, not a replacement for checking the answer.
Sources: TechCrunch, 3 November 2026; Anthropic research, 2 November 2026.
https://www.anthropic.com/research/provable-inference
Repost this before someone mistakes a receipt for a refund.
Thanks for supporting Lil'meme. Your support is appreciated.
The absurd
Why this is ridiculous
Even a wrong answer can have genuine paperwork.
The breakdown
How it breaks down
Math checks the reply against model settings locked in beforehand, without revealing them. Identity, not truth.
The upside
Why it could matter
Could help verify you got the model promised. No deployment planned.
Sources
https://techcrunch.com/2026/11/03/anthropic-is-working-on-a-system-to-prove-ai-models-identity/
One more Lilmeme?
Surprise me →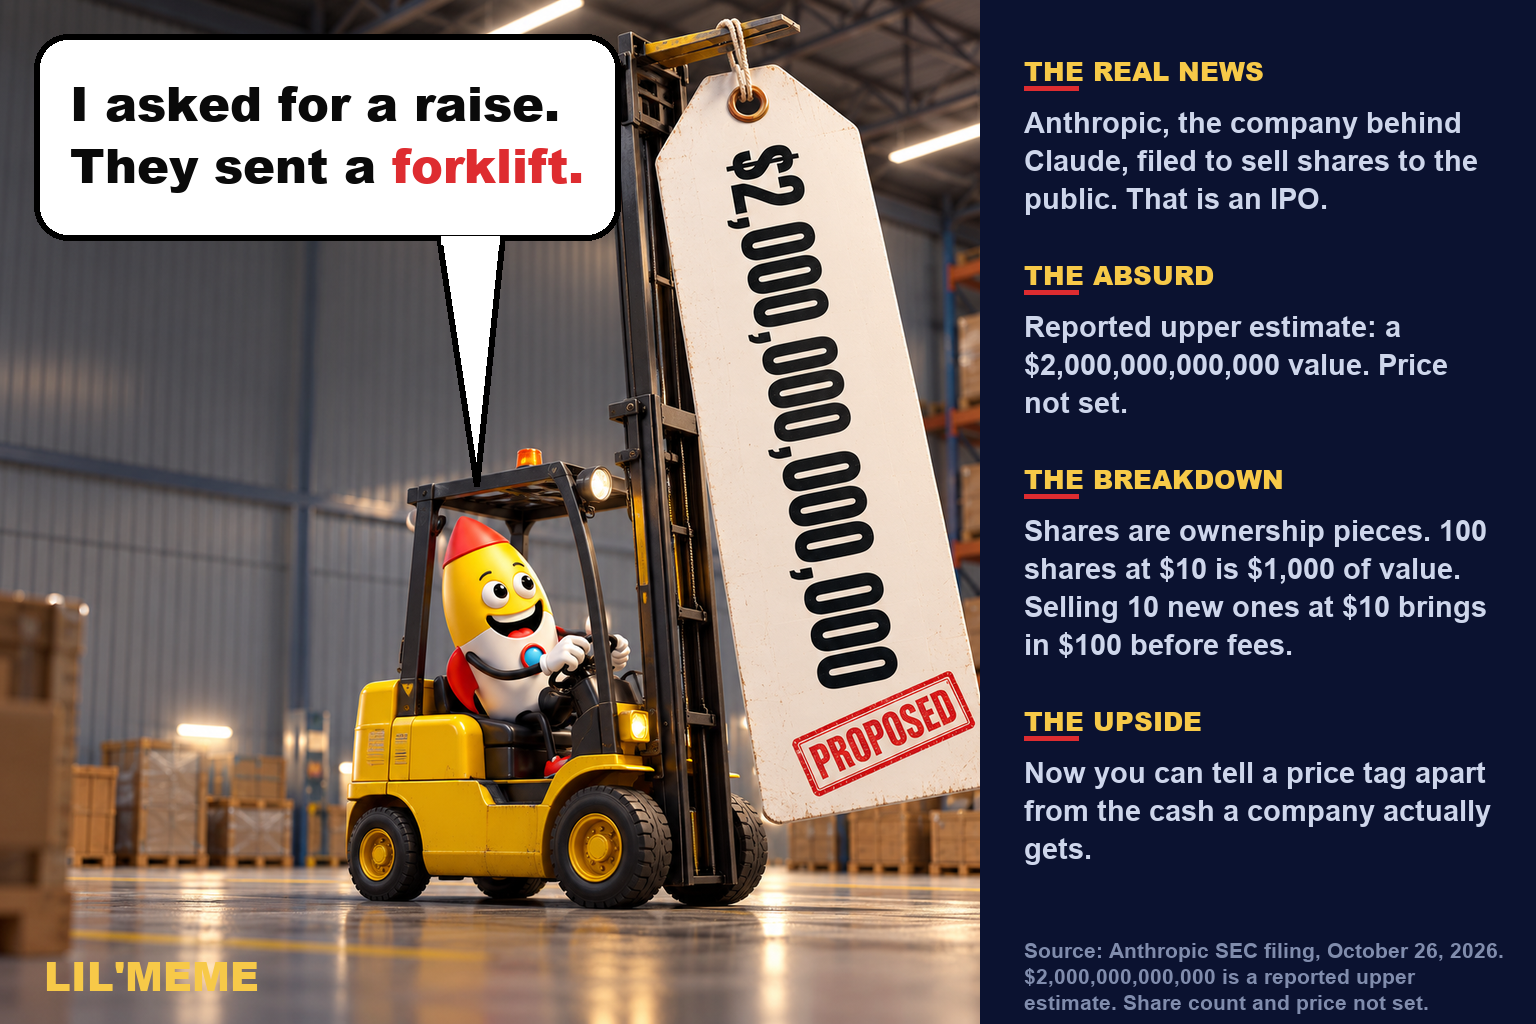
THE PRICE TAG NEEDS A FORKLIFT
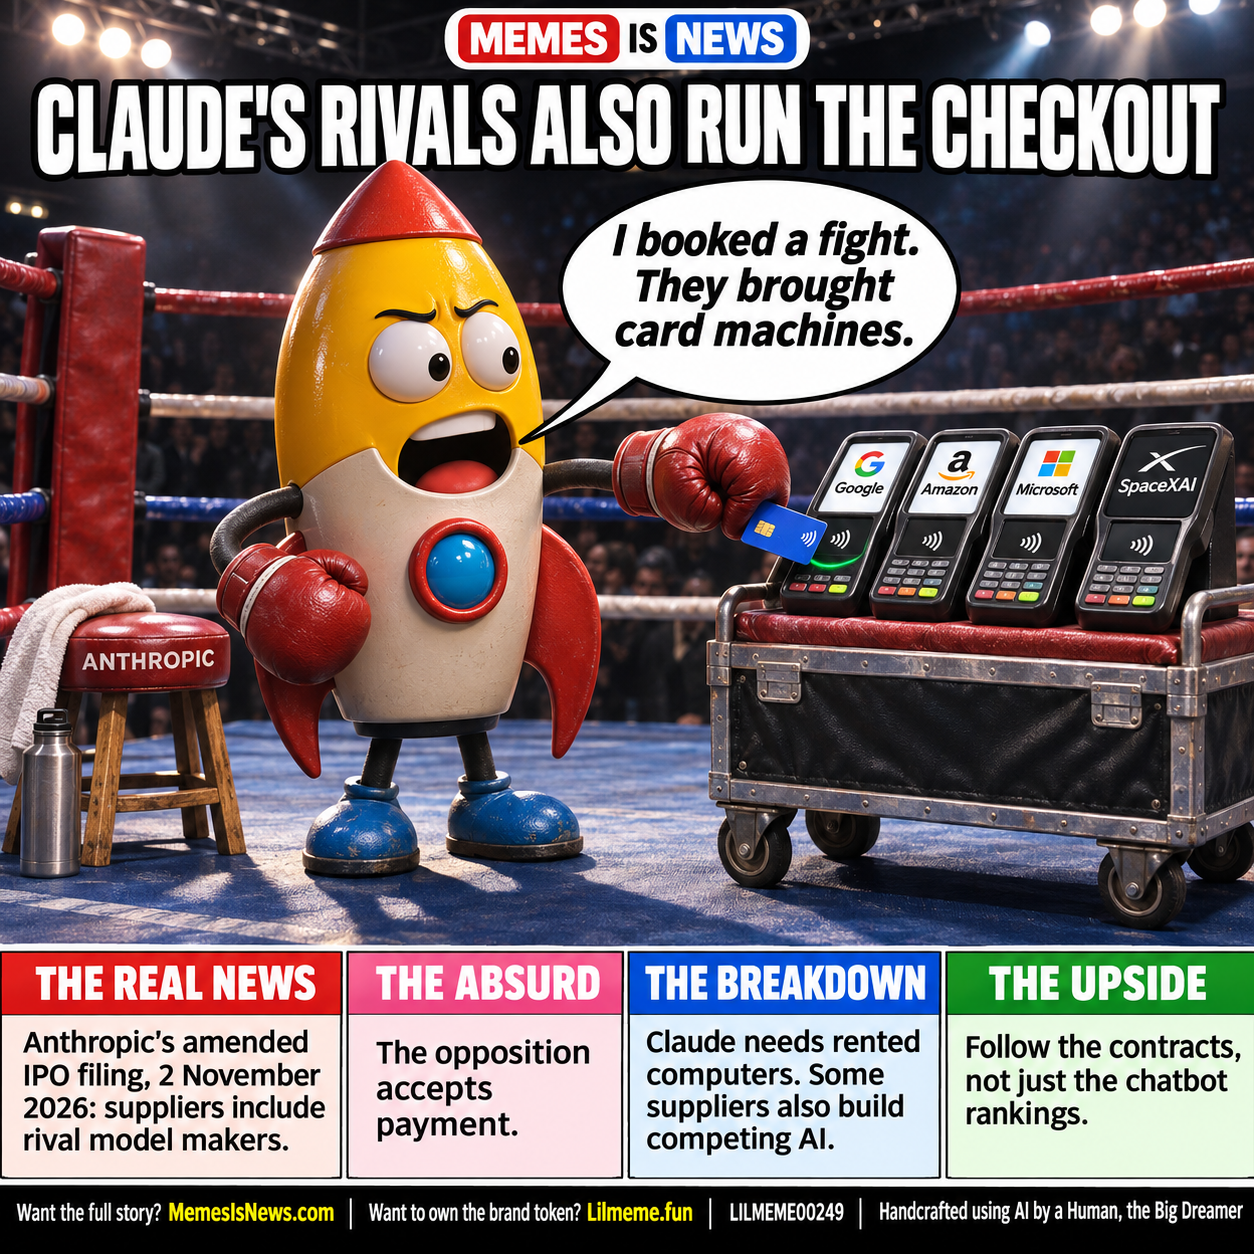
CLAUDE'S RIVALS ALSO RUN THE CHECKOUT
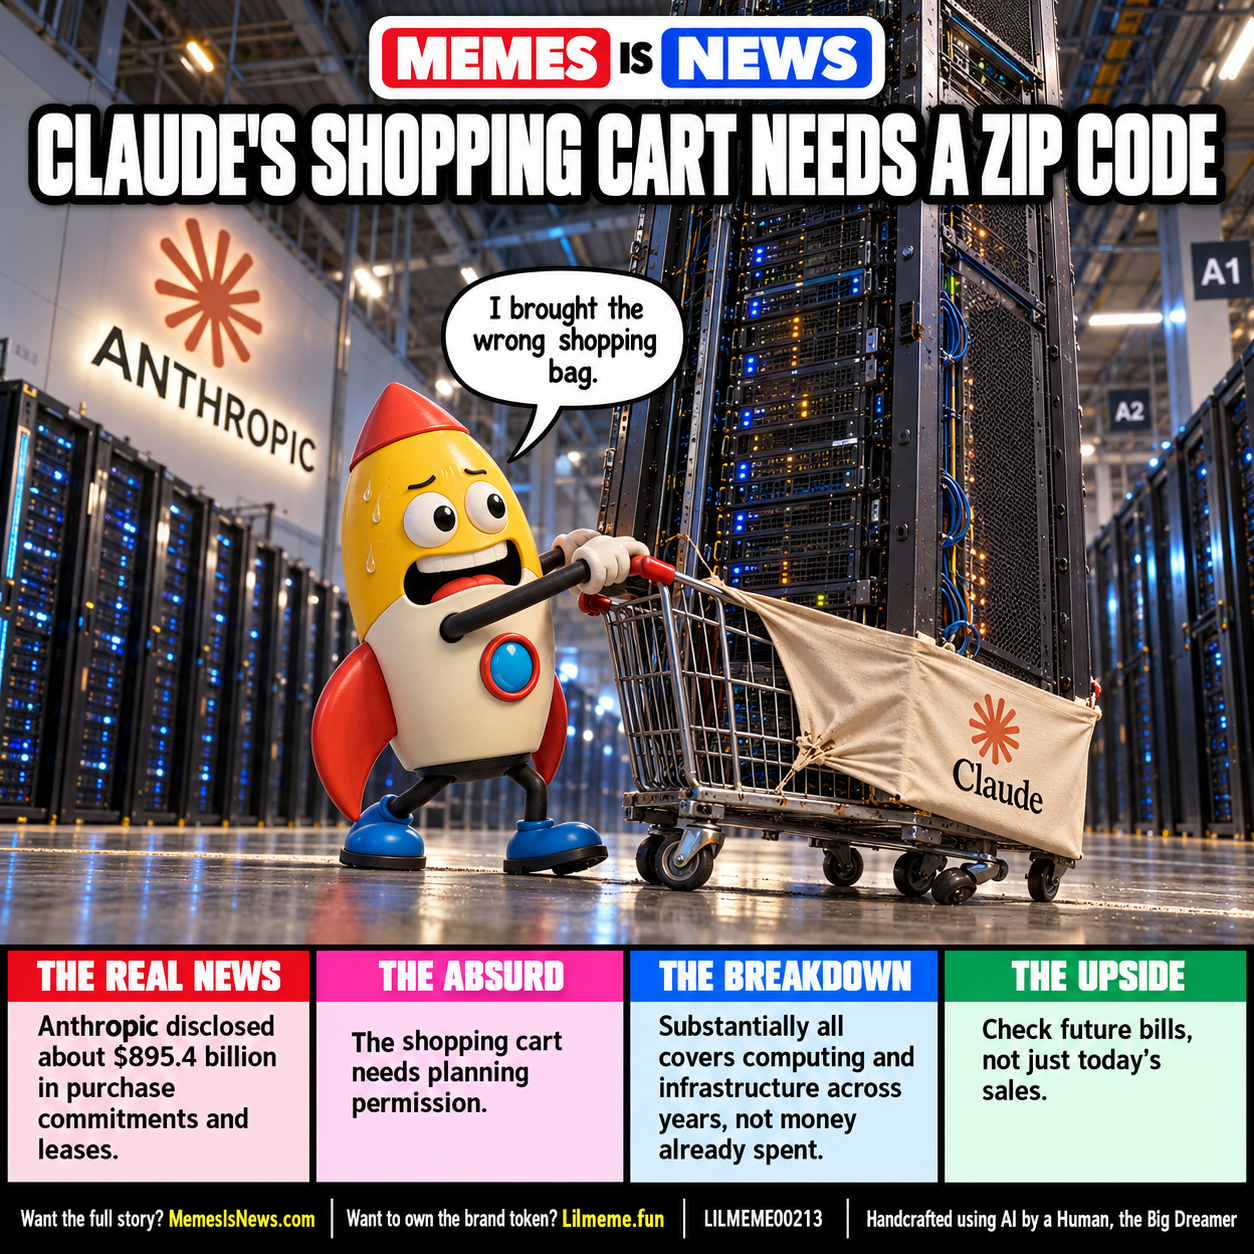
CLAUDE'S SHOPPING CART NEEDS A ZIP CODE
Get the next Lilmeme: the email digest, Follow on X or subscribe via RSS.