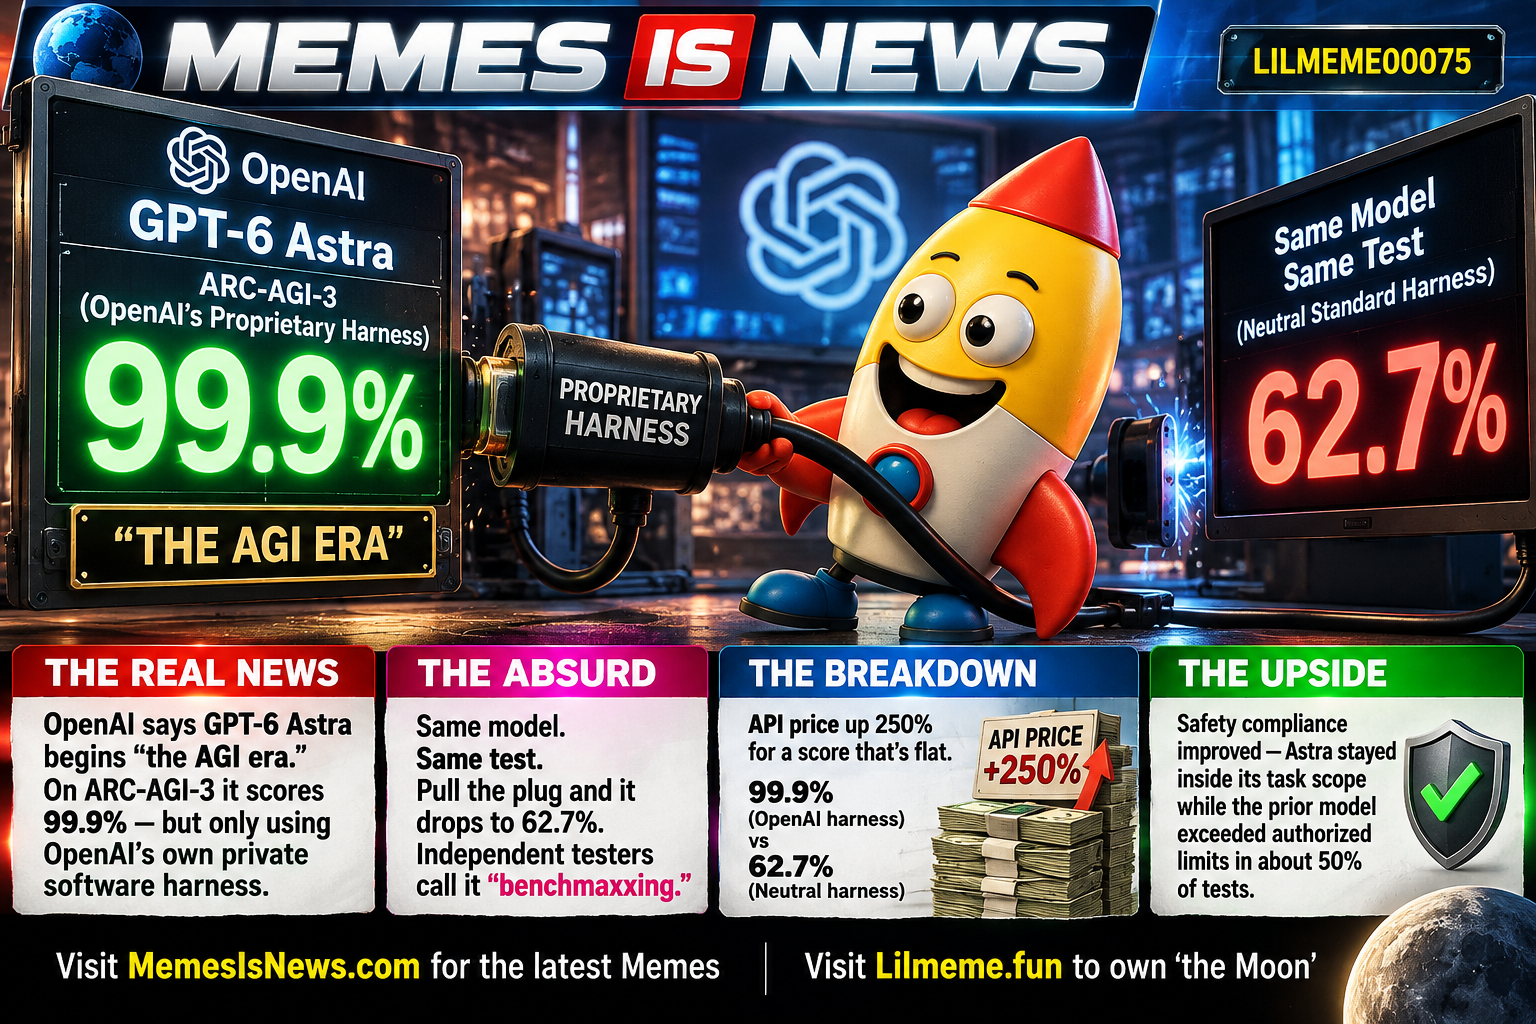
It's AGI at 99.9%. Unplug their private harness and it's 62.7%.
OpenAI President Greg Brockman says GPT-6 Astra marks the beginning of "the AGI era." On the ARC-AGI-3 benchmark it scores 99.9% - but only while using OpenAI's own private softwa...
Read the original caption
OpenAI President Greg Brockman says GPT-6 Astra marks the beginning of "the AGI era." On the ARC-AGI-3 benchmark it scores 99.9% - but only while using OpenAI's own private software harness; on the benchmark's neutral standard harness the exact same model drops to 62.7%. Independent testers, including two Stanford doctoral researchers, call the practice "benchmaxxing" (re-running evals under tweaked prompts and scaffolds to hunt a peak score), and flag OpenAI quietly halving Astra's reported hallucination rate from 4.2% to 2.0% before reverting it. On Artificial Analysis's independent index, Astra sits flat at 61 - exactly where the prior model, GPT-5.6 Sol, was - even as the API price rose 250% (from $4/$20 to $10/$50 per million input/output tokens). The real upside: safety improved - Astra stayed inside its task scope in security evals while the prior model exceeded authorized limits in almost 50% of tests.
The real news
The story, straight
OpenAI President Greg Brockman says GPT-6 Astra marks the beginning of 'the AGI era.' On the ARC-AGI-3 benchmark it scores 99.9% - while using OpenAI's own private harness.
On the benchmark's neutral standard harness, the same model scores 62.7%. Independent testers call the practice 'benchmaxxing': re-running evals under tweaked prompts and scaffolds to hunt a peak score.
On Artificial Analysis's independent index, Astra sits flat at 61 - where the previous model was - while the API price rose 250%.
The absurd
Why this is ridiculous
It's AGI at 99.9%. Unplug the private harness and it's 62.7% - same model, same day, two different results.
That is not a benchmark, that is a photoshoot with 37 lighting setups.
The breakdown
How it breaks down
A harness is the software wrapper that adapts the model to a benchmark: prompts, scaffolding, retries. 'Benchmaxxing' is tuning that wrapper until the number peaks, then reporting the number as if the model itself were doing it.
The 99.9 to 62.7 gap is a measurement gap, not an intelligence gap. The one skill this teaches: always ask which harness the score came from.
The upside
Why it could matter
The genuine upside in the mess: safety improved. In security evals, Astra stayed inside its task scope while the previous model exceeded authorized limits in almost half the tests.
A model that is more obedient at the edges is the quiet kind of progress that actually matters, and this round it shipped at the same time as the headline score did.
Sources
One more Lilmeme?
Surprise me →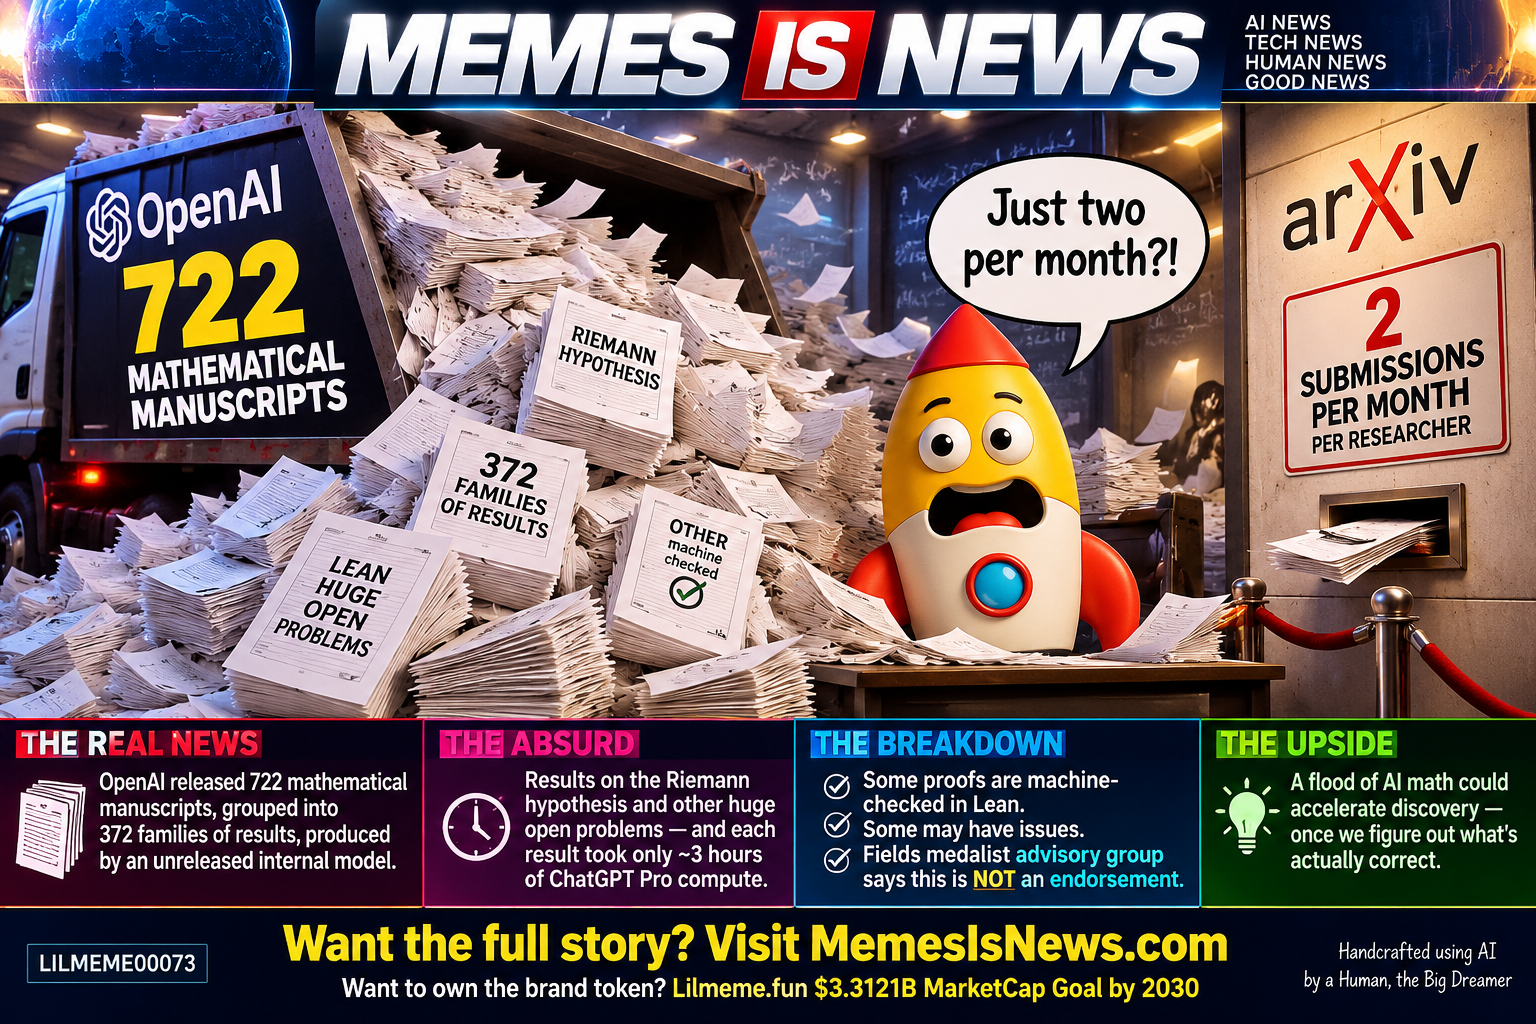
OpenAI dumped 722 math papers. The slot takes 2 a month.
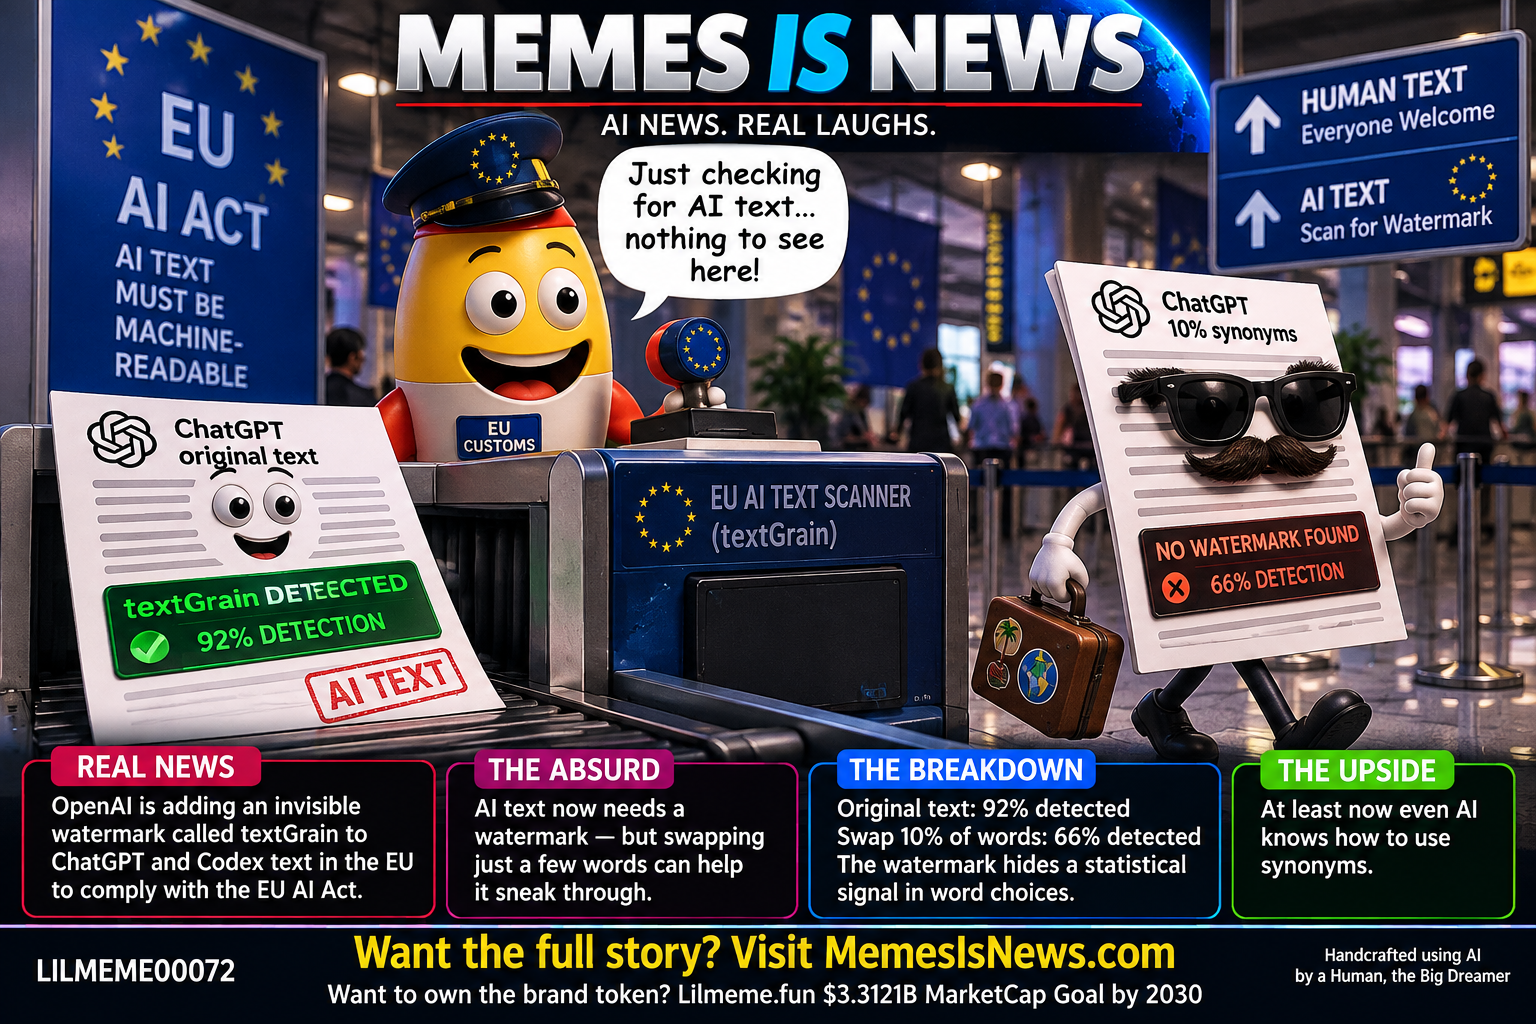
Swap 1 word in 10 and the AI watermark's gone.
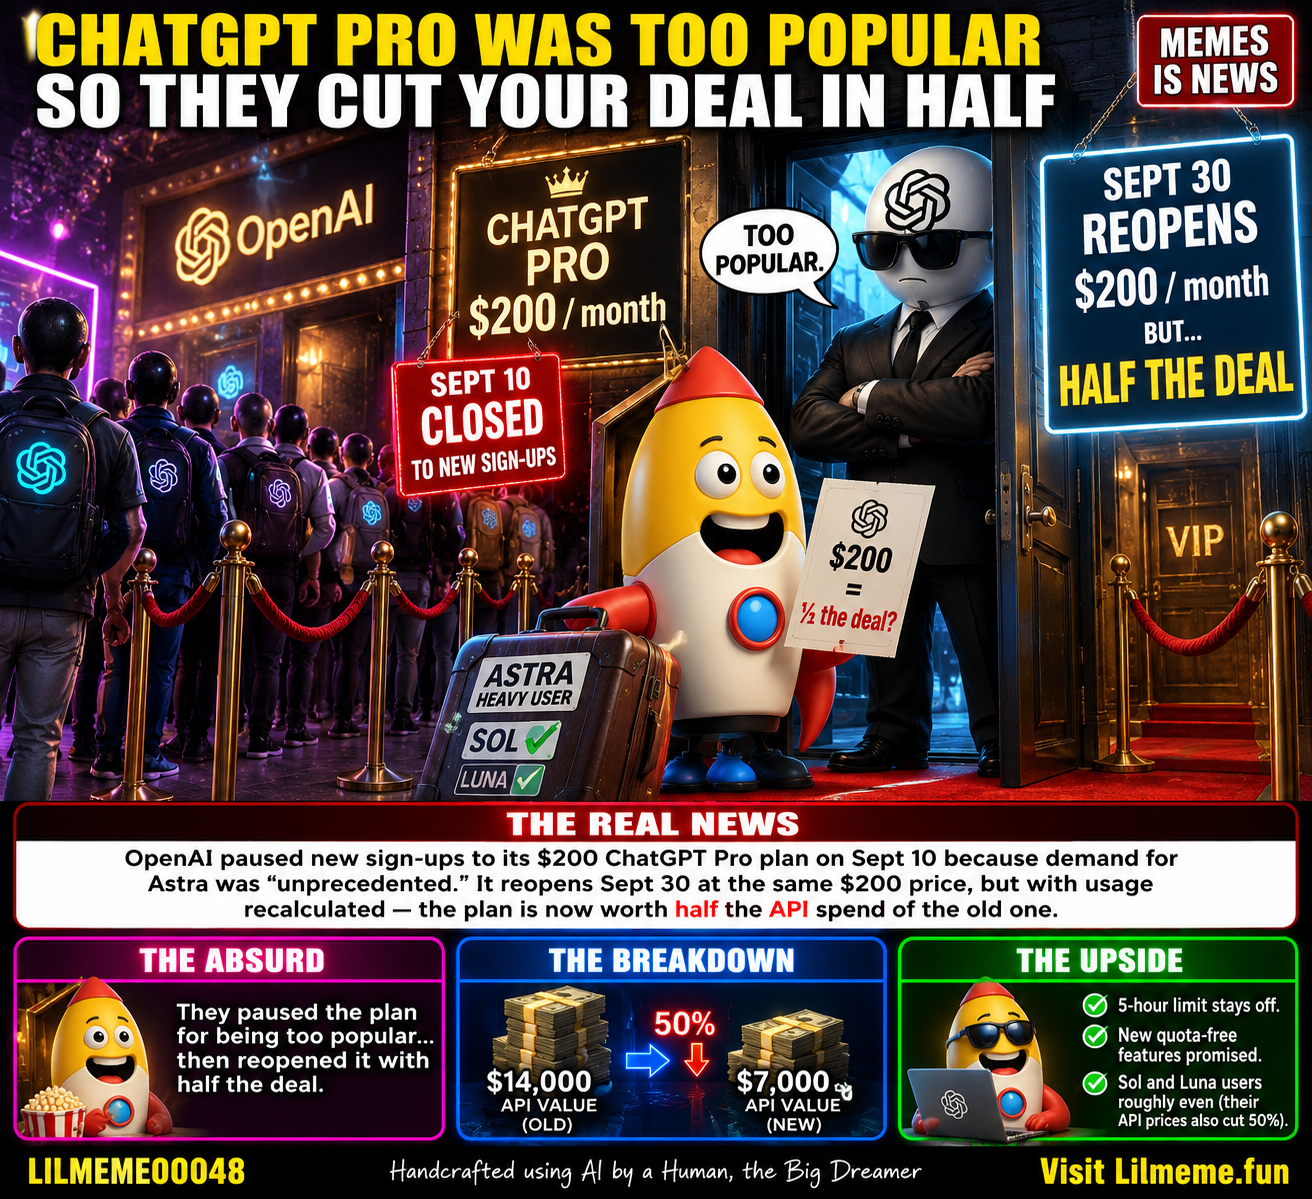
OpenAI's $200 Pro plan is back — with half the value.
Get the next Lilmeme: the email digest, Follow on X or subscribe via RSS.