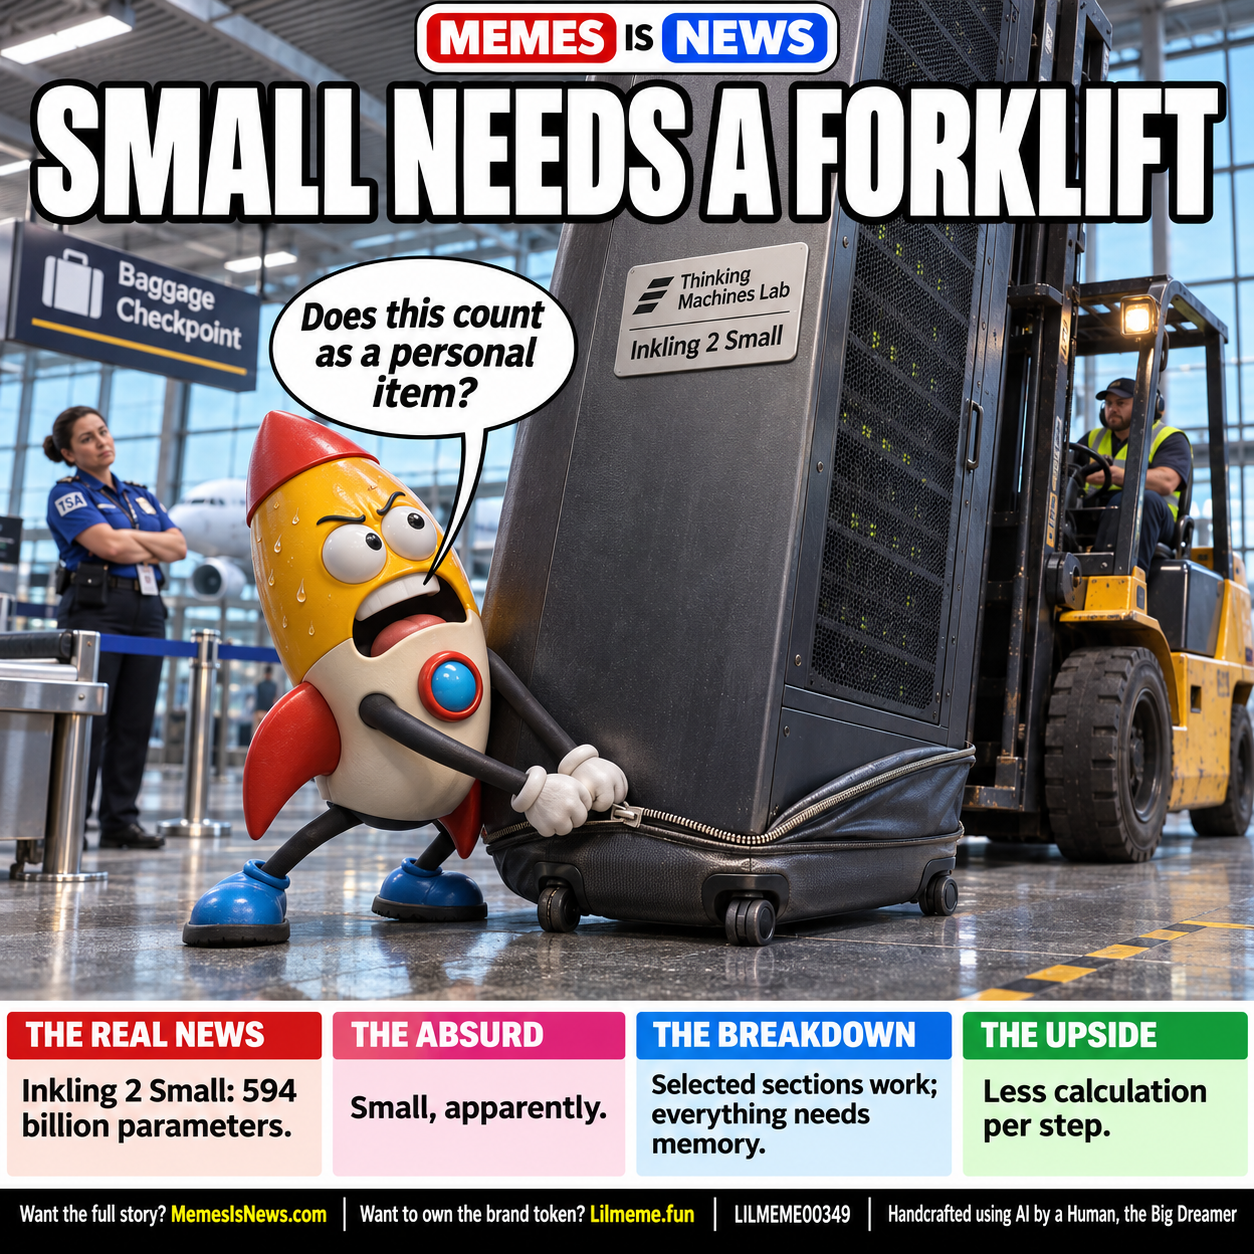
SMALL NEEDS A FORKLIFT
An AI model answers by processing text in chunks called tokens. Parameters are the learned settings behind its answers, not a headcount of tiny employees. Thinking Machines Lab in...
The real news
The story, straight
An AI model answers by processing text in chunks called tokens. Parameters are the learned settings behind its answers, not a headcount of tiny employees.
Thinking Machines Lab introduced Inkling 2 Small on Nov 5: 594 billion total parameters, with 17 billion active per token. Its earlier Inkling-Small had 276 billion total and 12 billion active.
The new Small is more than twice the old Small's total size.
Lil'meme is trying to fit this Small into a carry-on. The suitcase has requested structural engineering.
How does something that huge avoid doing all the work every time? A mixture of experts splits work among specialist sections: each token goes to 8 of 384 experts.
That cuts calculation; it doesn't erase the memory needed to hold the whole model. Think hotel: fewer rooms awake, same enormous building.
Artificial Analysis's Intelligence Index gives it 31, as cited in the announcement. That's a test score, not proof it wins every task.
It launched with closed weights through Tinker. Weights are the learned settings needed to run the model yourself.
The Nov 5 announcement says the company intends to release them under Apache 2.0 the following week, after external safety testing and red-teaming. An intention is not a completed release.
The useful lesson: compare active work, memory needs and actual availability, not the adjective on the box. Small is a name, not a luggage allowance.
Like or repost if your carry-on also needs a loading dock.
Thanks for supporting Lil'meme. Your support is appreciated.
The absurd
Why this is ridiculous
Small, apparently.
The breakdown
How it breaks down
Selected sections work; everything needs memory.
The upside
Why it could matter
Less calculation per step.
Sources
One more Lilmeme?
Surprise me →
Get the next Lilmeme: the email digest, Follow on X or subscribe via RSS.